01 / Description
Robotics VLA
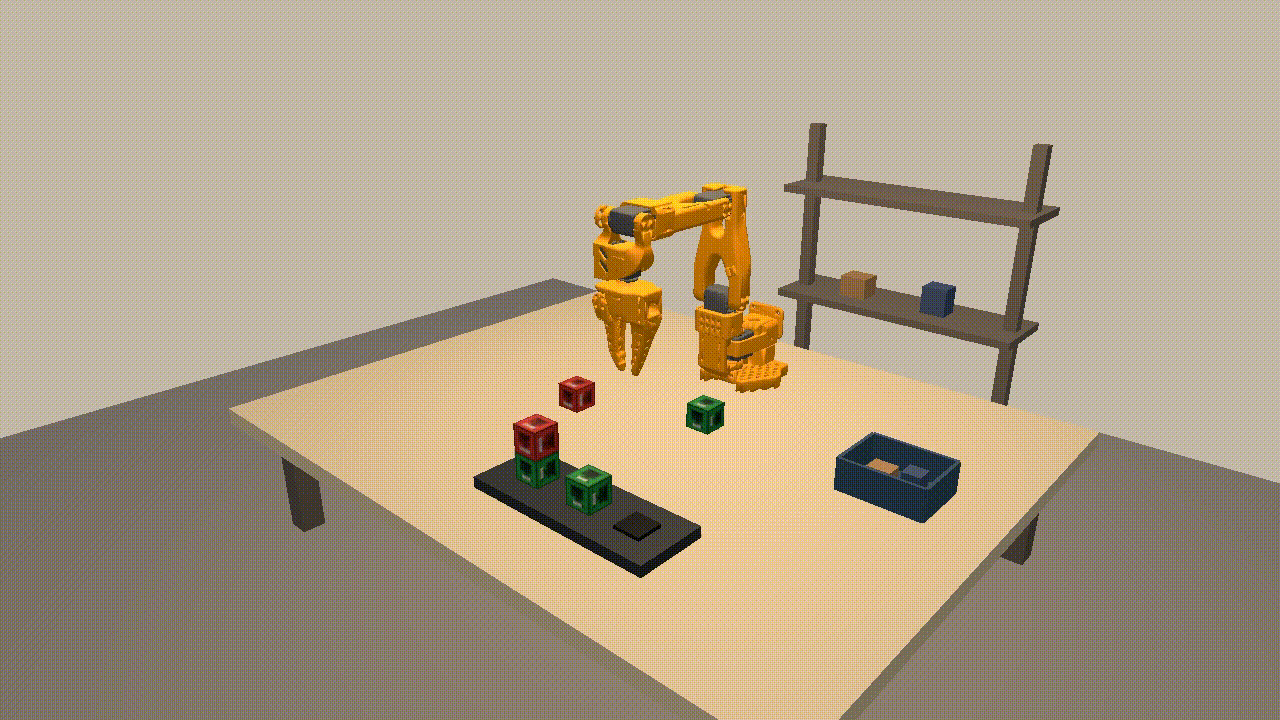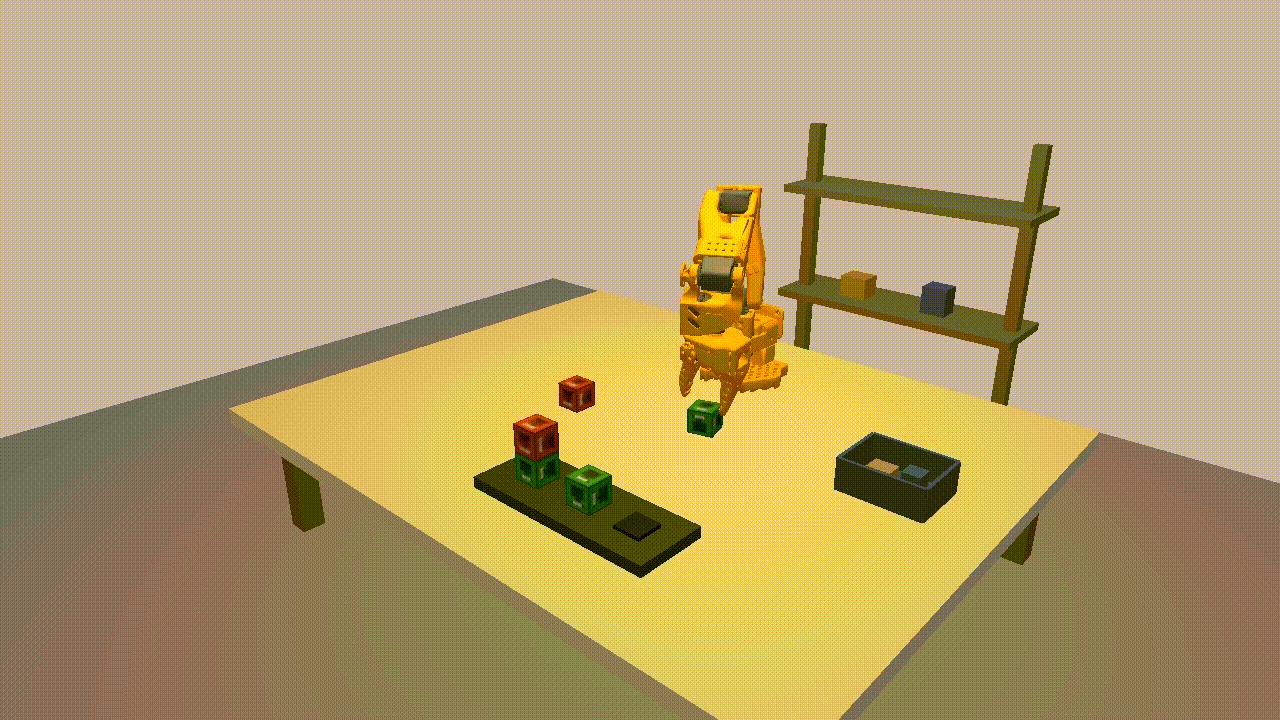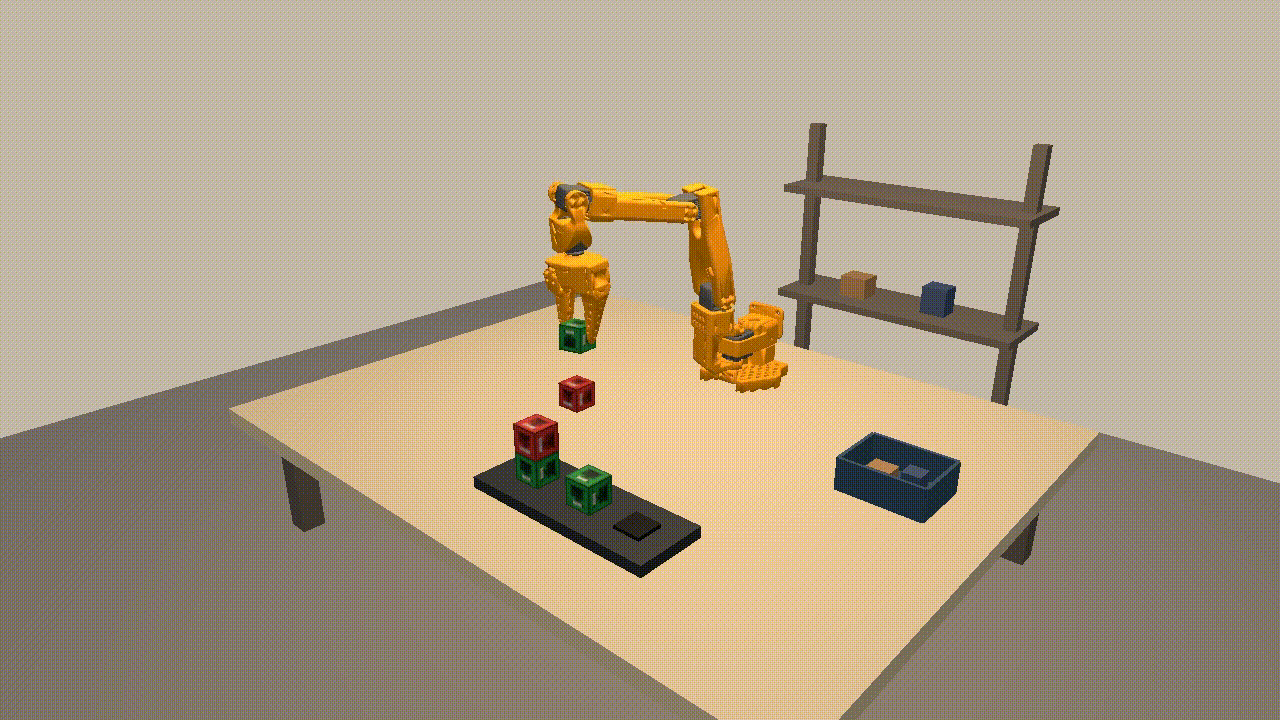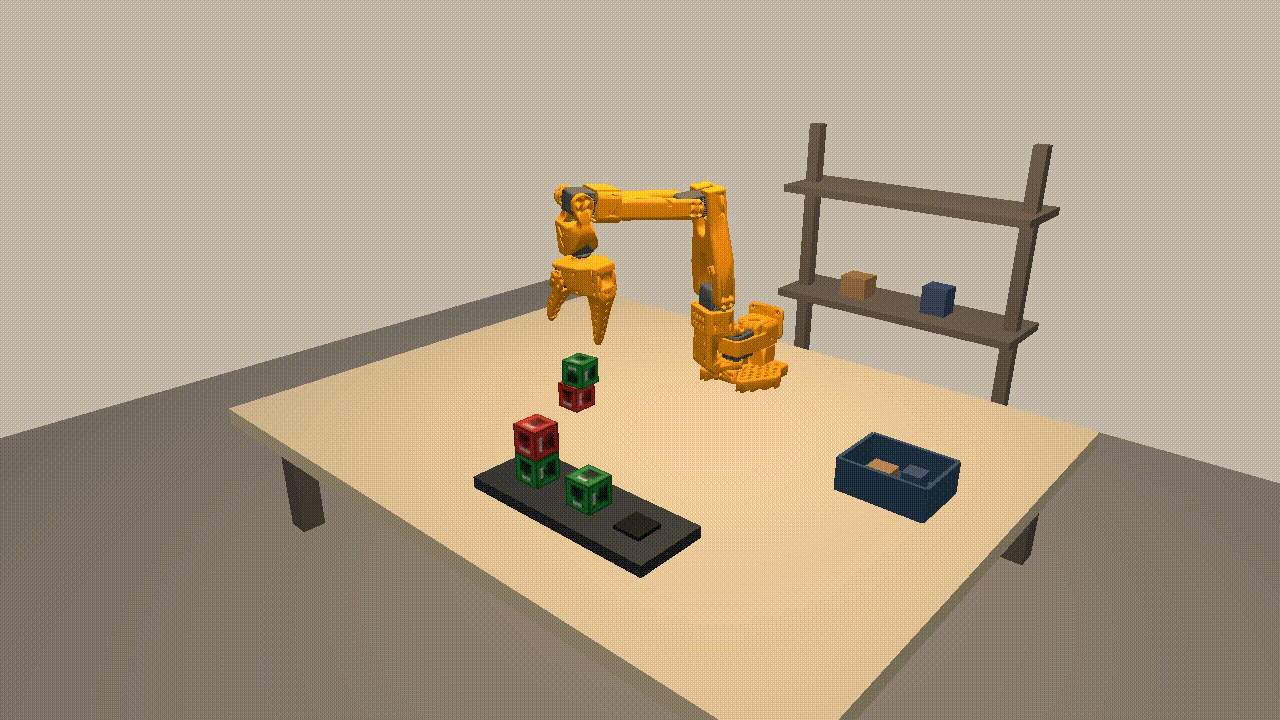
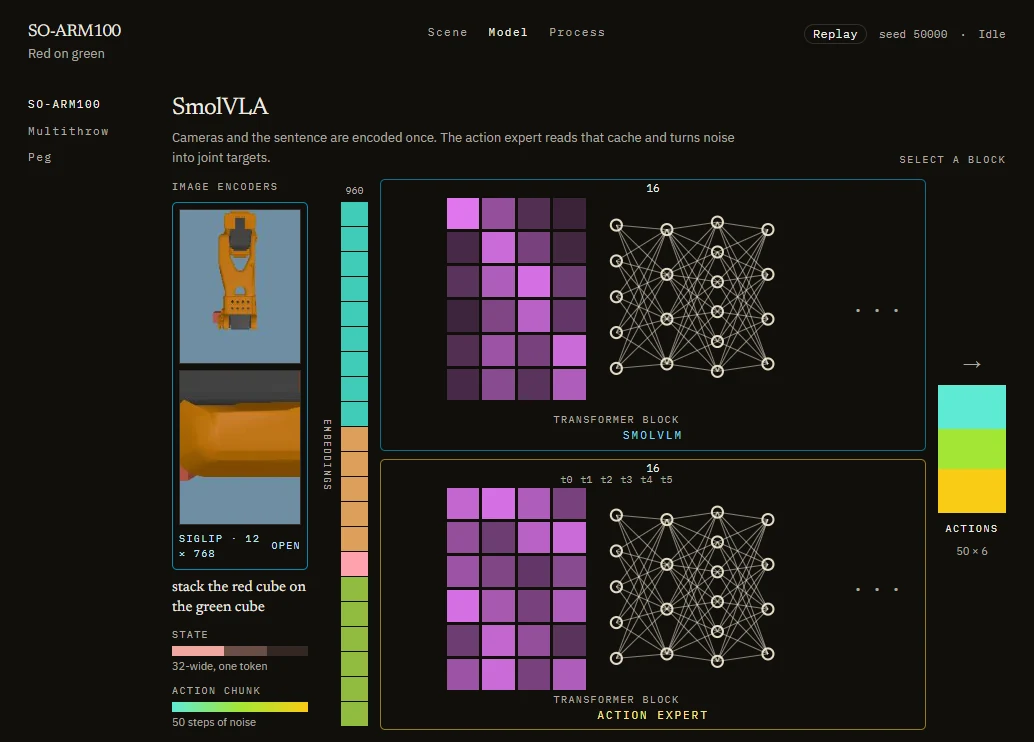
Fine-tuned the SmolVLA (450M) action expert to follow language commands, with attention visualized across 16 layers and a 7-joint MuJoCo simulator.
- PyTorch
- SmolVLA
- MuJoCo
- Gymnasium
- React
- Three.js
- grasp success
- 9/10
- stack success
- 5/10
- bin throws (scripted expert)
- 87%
- peg insertion (scripted expert)
- 90%
Problem
A robot policy that only repeats one trained motion is not useful. The goal was a policy that takes a plain-language command and acts on it, plus a way to see what the model attends to while it does.
Approach
I fine-tuned the action expert of SmolVLA (450M parameters) on demonstrations to follow language commands. To generate demonstrations and evaluate, I wrote a 7-joint arm simulator in MuJoCo with a Gymnasium interface and PyTorch, driven by scripted experts. A React and Three.js app visualizes the model's attention across all 16 layers.
Key technical decision
Fine-tune only the action expert rather than the full model. It keeps the pretrained vision-language backbone intact and makes training practical at this scale.
Result
The fine-tuned policy grasps 9 of 10 times and stacks 5 of 10 times when given a language command. The scripted experts that generate the data reach 87% on bin throws and 90% on peg insertion.